Bayesian BM25
BM25 that knows what it doesn't know.
BM25 is a point-estimate ranking function: it reads document frequency, average length and two tuning constants off the corpus and treats them as fact. On rare terms, short fields and small or cold collections those estimates are noisy, and the ranking gets unstable. Bayesian BM25 puts priors on those statistics, shrinking thin evidence toward the corpus and learning its parameters with uncertainty instead of one global guess.
What the prior buys you
Why a Bayesian treatment beats a tuned constant.
Calibrated on rare terms
Classic BM25 derives its IDF from a point estimate of document frequency. On long-tail terms (the ones that appear in a handful of documents), that estimate is noisy and a single rare word can dominate the ranking. A prior shrinks sparse statistics toward the corpus, so rare terms score sensibly instead of swinging the result set.
Stable on small & cold corpora
A fresh index, a new tenant or a narrow field has too little data for reliable averages. Bayesian smoothing borrows strength from corpus-level priors until enough evidence accumulates, so search quality does not collapse on day one and converges as the collection grows.
Parameters with uncertainty
The k1 and b knobs stop being two hand-tuned global constants. They are estimated with credible intervals, so the model knows when it has too little data to be confident, and falls back on the prior rather than overfitting to a thin sample.
Per-field, per-tenant
Title, body and metadata fields have very different length and frequency distributions. Each gets its own posterior instead of one compromise setting forced across the whole index, and each tenant’s corpus tunes itself.
Graceful with length
Length normalization adapts to the field’s actual length distribution rather than measuring every short and long document against one global average, so abstracts and full reports are scored on their own terms.
Drops into hybrid retrieval
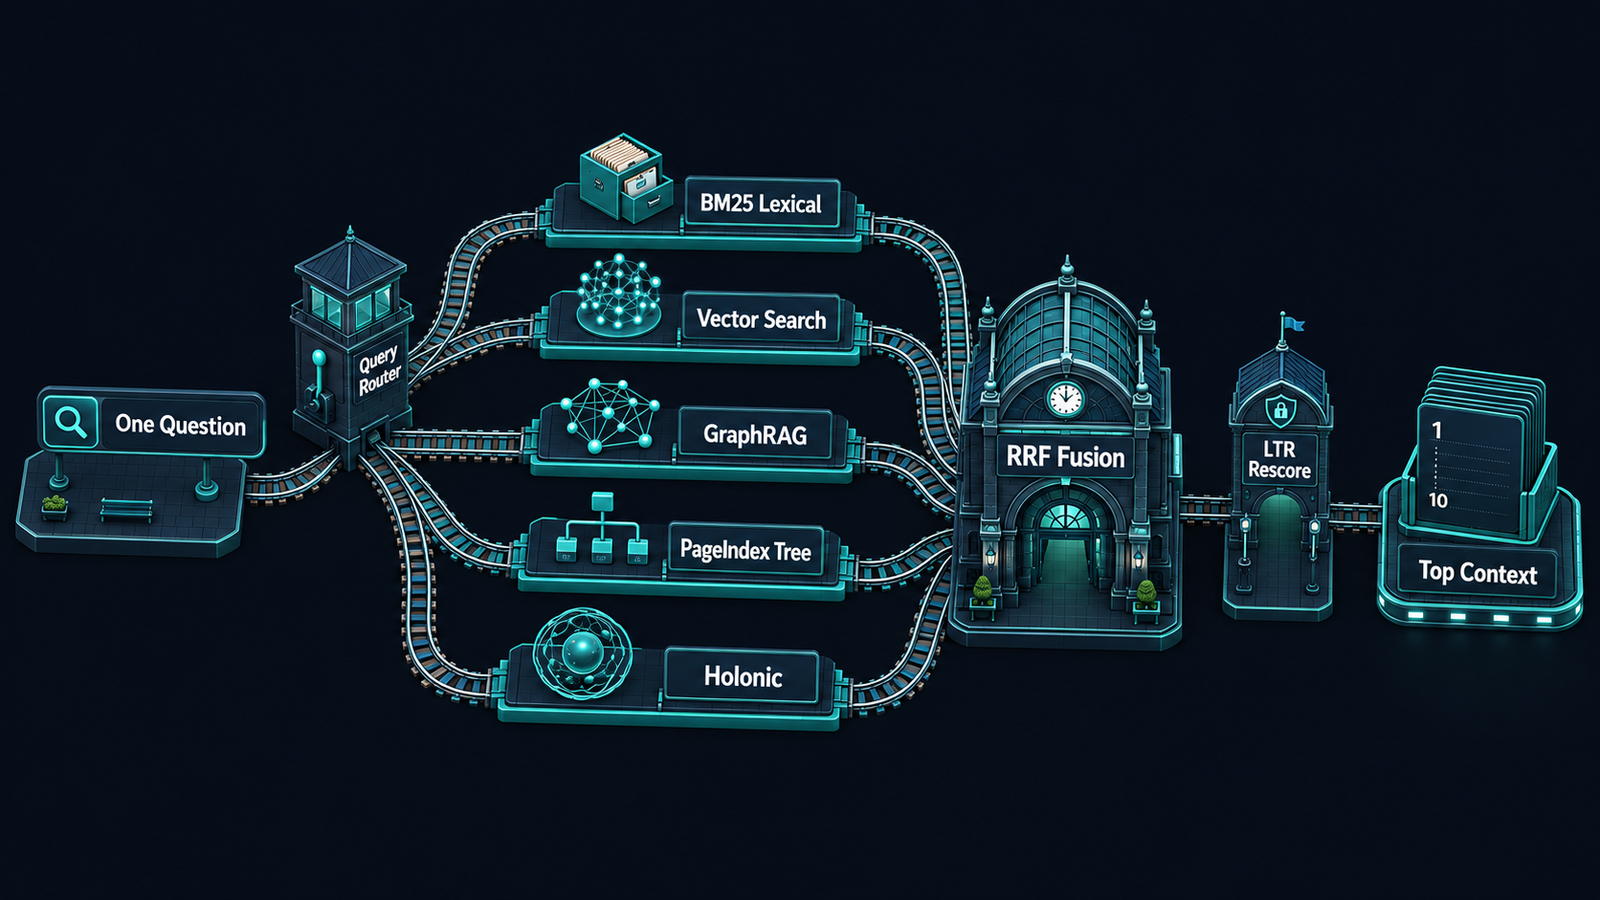
It is still BM25: the same inverted index, fused by RRF with dense-vector and graph-context signals. The Bayesian layer changes how the lexical scores are estimated, not the retrieval architecture around them.
Part of hybrid retrieval
Lexical precision, calibrated.
Dense vectors find what you mean; lexical search finds what you said. Bayesian BM25 keeps the lexical half honest, stable on the rare, exact terms that matter most in legal, government and technical corpora, before RRF fuses it with vector and graph signals into one ranked, citation-backed result.